Feedback and Robust Local Readout of a Fixed Four-State Quantum Source
Adaptive phase readers: exact scope, optimum and genuine feedback gain
Adaptive phase readers: exact scope, optimum and genuine feedback gain
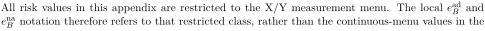
Searchable transcription
All risk values in this appendix are restricted to the X/Y measurement menu. The local ead
B and
ena
B notation therefore refers to that restricted class, rather than the continuous-menu values in the
main text. A difference between these values is a change of admitted access. The fixed-schedule analysis optimized one fixed X/Y allocation and its terminal decoder. We enlarge the admitted class to nonanticipating sequential choices between those same two readers, allowing classical randomization. This changes two resources: a schedule may already be randomized before any observation, and feedback may select later settings using observed records. We separate these effects. The ideal gain below comes entirely from schedule randomization; the specified-noise gain survives comparison with every randomized nonadaptive schedule and therefore is a genuine feedback advantage.
Declared operational experiment and symmetry
The source is the fixed-schedule preparation family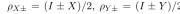 2 with the nominated binary sign target. A label
 is held fixed and an admitted independent stock

 supplies one copy per tick. The inaccessible preparation controller retains
 ; it is not supplied to the decoder. Every trial chooses
 on a fresh copy, with the same terminal effects
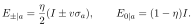
Searchable transcription
E±|a = η
2(I ± vσa),
E0|a = (1 −η)I.
The phase rotation, beam splitter, calibrated detector, timing and unread baths retain the fixed-schedule physical contract. The experiment always outputs a sign at the fixed deadline , includes all nulls, and neither postselects clicks nor claims a full retained-quantum-channel equivalence. A policy may use earlier accessible records and independent ready coins. No collective POVM, another basis, returning environment or readable preparation record is admitted. Stopping early and retaining an irrevocable decision can be represented by ignoring subsequent records, but no saved-copy or random-stopping resource optimum is asserted. For equal axis efficiencies and visibilities, the experiment is invariant under the four-element group generated by exchanging X/Y and reversing all signs. Sign reversal also reverses the target and final decision. This group acts transitively on the four source labels. Consequently the uniform source prior is least favourable for the complete randomized policy class: every minimax risk is at least its optimal uniform-prior Bayes risk, while averaging a Bayes optimal policy over the group makes each of its four errors equal to that Bayes risk. The group transformation is selected before the experiment and translated into actual settings, record signs and terminal decisions; it is not knowledge of the hidden source. Two independent fair root-control bits suffice for this group choice; a terminal posterior tie may additionally consume a fresh fair decision bit. This standard symmetrization argument applies both to adaptive policies and to the smaller randomized-nonadaptive class.
An all-horizon ideal theorem
Theorem A.1 (Ideal adaptive minimax value and its source of improvement). With , the optimal uniform-prior Bayes risk and randomized adaptive minimax risk are equal, and
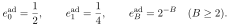
Searchable transcription
ead
0 = 1
2,
ead
1 = 1
4,
ead
B = 2−B
(B ≥2).
For every a randomized nonadaptive schedule attains the same value: choose equally between the allocations
 and
 and use uniform-prior Bayes terminal decisions, with symmetric tie handling. Therefore ideal feedback supplies no further gain over randomized schedules.
Proof. Use unnormalized nonnegative hypothesis weights; terminal Bayes loss is min
 ). Every arbitrary adaptive tree is covered by choosing either X or Y at its root, summing the optimum losses of its two outcome branches, and recursing. Randomizing an action cannot improve a minimum of these two conditional losses.
The nontrivial reachable states, up to axis and sign symmetries, have three forms. Opposite-target two-state weights on different axes have remaining-
 loss min
 : the next two choices give min
 min
 ) for one step, and induction gives the same halving relation for every
 . A pair of equal weights
 on opposite signs of one axis has loss
 at
 = 0 and zero for
 1, by measuring that axis. Finally consider
 ) with
 . Its loss is
 at
 1, and
 for
 2. Indeed, measuring X gives branches
 2) and the equal Y pair (
 2); measuring Y gives one single-target branch and the opposite-target pair (
 ). The preceding formulas prove the claimed values by induction. This exhausts the successors of these types, so it is a lower bound for every decision tree as well as an attainable recursion. Start with weights (1
 1). Either first reader gives two symmetric
 2) branches. The formulas just proved, divided by total prior mass four, give 1
 4 for
 2 and 2
 for
 3. The symmetry argument then supplies the minimax equality. For a fixed allocation with positive counts, the only opposite-target ambiguous corners have likelihoods
 and
 . Their uniform-prior Bayes contribution is min

 1) this is 2
 . Axis/sign symmetrization equalizes the four risks and retains a nonadaptive schedule, proving attainment in the smaller class.
Thus a one-percent target needs seven ideal fresh copies in the enlarged randomized class, rather than eight in the fixed-schedule single-allocation class (and twelve for balanced fixed schedules). At  = 8, the enlarged optimum is 1
 256, rather than 1
 130. This gain is explicitly attributed to admitted schedule randomization, not feedback. The target is still not perfectly identifiable from any finite record. There is also a horizon-consistent feedback realization useful for erasures: choose an initial axis fairly, read it until its first opposing sign, then read the other axis on the next click. That other-axis result determines the sign. If all available clicks agree, return their common sign; if the first opposing sign is the last click, use a fair guess; with no clicks also guess fairly. Conditional on
 2 clicks, an initially aligned reader makes no error. An initially cross-axis reader errs only on an all-equal sequence or a first flip at the last click, each of probability 2
 and error 1
 2. Averaging the initial axis gives
 . For
 = 1 it gives 1
 4 and for
 2. The erasure extension is developed separately, preserving its additional independence and access premises.
Exact noisy Bellman certificates
For rational calibrated , put every outcome likelihood over a common positive denominator
 . Let
 be its nonnegative integer numerator. For unnormalized integer weights
 , define
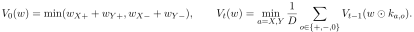
Searchable transcription
V0(w) = min(wX+ + wY +, wX−+ wY −),
Vt(w) = min
a=X,Y
1
D
∑︂
o∈{+,−,0}
Vt−1(w ⊙ka,o).
Homogeneity permits dividing by its integer gcd and storing one rational value per resulting state. The minimum covers every adaptive action, not only the actions chosen by the exported policy. The uniform Bayes lower bound is
 4. A policy selecting a minimizing action and a terminal Bayes sign attains it; group averaging supplies the matching per-label minimax upper bound. This proves the recursion for the full declared policy class, not only a numerical ansatz or one nominated prior policy. The exported JSON certificate stores all recursively required normalized states, both action values, the selected action and terminal losses. A checker verifies every Bellman equality bottom-up using exact fractions, then checks the root value. The producer separately evaluates the policy’s four individual errors. There is no floating convergence criterion. Nominally impossible histories have a declared default
X action and fair terminal guess, so the policy remains defined before an actual-device perturbation is applied. For 10, the common denominator is
 = 25 and the X-reader numerators for +
 are respectively (19
 10) and (5
 5); exchange axes for Y. The following exact comparisons use identical copy budgets, reader effects, null retention and independent stock. The nonadaptive comparator includes all fixed counts and arbitrary root schedule randomization, not just the fixed-schedule single-schedule minimax design.
 Adaptive minimax Randomized nonadaptive minimax Best counts 4


 8
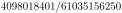
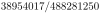

At eight copies these are approximately 0 06714193348 and 0
 07977782682. Their strict difference is a genuine feedback gain. The fixed single-schedule value 0
 08270910464 is a third, narrower comparison and is not used to exaggerate that gain. The specified-noise model also supplies a copy threshold. Its adaptive errors at budgets eighteen and nineteen are respectively
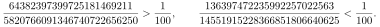
Searchable transcription
64382397399725181469211
5820766091346740722656250 >
1
100,
136397472235992257022563
14551915228366851806640625 <
1
100.
The best randomized-nonadaptive errors at budgets twenty and twenty-one are respectively
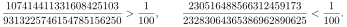
Searchable transcription
107414411331608425103
9313225746154785156250 >
1
100,
230516488566312459173
23283064365386962890625 <
1
100.
The latter minimizing counts are (9 11) at twenty and (9
 12) at twenty-one, with their axis swaps. Extra observations can always be ignored, so risks are nonincreasing in budget. These adjacent certified comparisons prove that the one-percent threshold is exactly nineteen adaptive copies versus twenty-one randomized-nonadaptive copies in this calibrated noise model. They do not inherit the separate ideal-erasure robustness contract. The source-copy savings are not automatically total apparatus savings: the adaptive reader consumes additional causal control capability. To justify the nonadaptive optimum, group symmetry again reduces minimax to uniform-prior Bayes loss. A randomized mixture of fixed schedules has Bayes loss at least the smallest Bayes loss of one component. For each count pair, ordered-record exchangeability permits the exact histogram likelihood calculation. Minimizing its uniform-prior loss over all
 counts, then symmetrizing its minimizing schedule, supplies matching lower and upper bounds for the whole randomized-nonadaptive class.