Technical Companion: Detector Interfaces and Retained Outputs
Two-template monitoring and task-relative conditional-error certification
Two-template monitoring and task-relative conditional-error certification
The same conditional-device contract, a smaller task
Let ) be any conditional three-outcome POVM on a finite-dimensional input space, summing to identity. Qutrit vacuum and occupied modes are an example. The POVM is independent of the current probe’s classical preparation tag; the probe affects it through its quantum state only. The actual conditional input and inert reference are independent of the device’s ready stock. Uncontrolled input/stock correlation is outside the linear effect representation. Nominate normalized density matrices
 and trusted probe preparations within trace distance
 of them in every calibration trial. Future actual label-conditioned marginals must lie within
 of
 . These are independently admitted preparation conditions, not conclusions of the unknown detector. Effects may depend on all preceding accessible history. Admit pathwise operator-norm drift envelopes
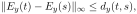

A common rate model is , with
 in inverse clock slots (or use actual seconds and rates per second). Every calibration, production and waiting slot consumes that clock. The envelopes must constrain actual conditional effects, not only an averaged master equation. Neither probes nor resets establish the envelopes. In a trial of template
 , record all three outcomes. Let
 indicate a wrong conclusive label,
 a correct conclusive label, and
 any conclusive label. Nulls have
 = 0. For threshold

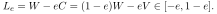
Thus it has range length one, even if clicks are rare. No clicked-only sample selection or Bernoulli assumption on thinned clicks is used. All raw outcomes, settings, times and calibration/deploy decisions are part of the physical retained record. The numerical supplement supplies aggregated synthetic count tables, not an ordered experimental archive.
One event certifies all thresholds and all inspected prefixes
Permit at most epochs, opened adaptively. Each epoch may use any predictable template schedule and a declared finite budget. For
 1 uses of one template, let hats denote empirical means and bars the averages of their true conditional means. Set
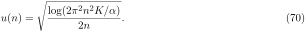
Searchable transcription
s
log(2π2n2K/α)
u(n) =
2n
.
(70)
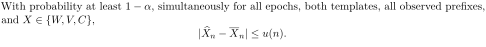
Searchable transcription
With probability at least 1 −α, simultaneously for all epochs, both templates, all observed prefixes,
and X ∈{W, V, C},
| bXn −Xn| ≤u(n).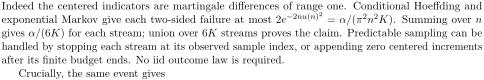
Searchable transcription
Indeed the centered indicators are martingale differences of range one. Conditional Hoeffding and
exponential Markov give each two-sided failure at most 2e−2nu(n)2 = α/(π2n2K). Summing over n
gives α/(6K) for each stream; union over 6K streams proves the claim. Predictable sampling can be
handled by stopping each stream at its observed sample index, or appending zero centered increments
after its finite budget ends. No iid outcome law is required.
Crucially, the same event gives
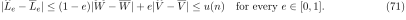
Searchable transcription
|bLe −Le| ≤(1 −e)|c
W −W| + e| bV −V | ≤u(n)
for every e ∈[0, 1].
(71)
There is no threshold-grid union cost and an error target can be chosen after observing the retained data. The third counter supplies a separate range-one conclusive-rate bound rather than the looser sum of two counter errors. At a future deployment time
 after template-
 probes at times
 , define
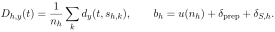
Searchable transcription
Dh,y(t) = 1
X
k
dy(t, sh,k),
bh = u(nh) + δprep + δS,h.
nh
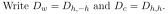
Searchable transcription
Write Dw = Dh,−h and Dc = Dh,h.
Theorem 9.1 (Direct general-reader deployment certificate). On the simultaneous event, every actual label-conditioned future input obeys
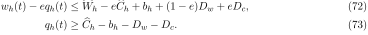
Searchable transcription
wh(t) −eqh(t) ≤c
Wh −e bCh + bh + (1 −e)Dw + eDc,
(72)
qh(t) ≥bCh −bh −Dw −Dc.
(73)
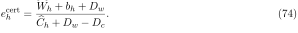
If the latter lower bound is positive, define
Searchable transcription
ecert
h
=
c
Wh + bh + Dw
bCh + Dw −Dc
.
(74)
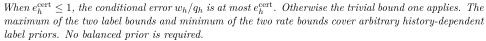
Searchable transcription
When ecert
h
≤1, the conditional error wh/qh is at most ecert
h
. Otherwise the trivial bound one applies. The
maximum of the two label bounds and minimum of the two rate bounds cover arbitrary history-dependent
label priors. No balanced prior is required.
Searchable transcription
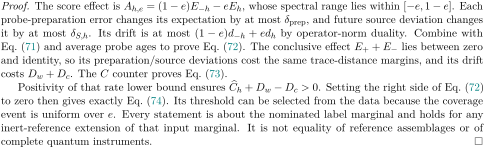
Proof. The score effect is Ah,e = (1 −e)E−h −eEh, whose spectral range lies within [−e, 1 −e]. Each
probe-preparation error changes its expectation by at most δprep, and future source deviation changes
it by at most δS,h. Its drift is at most (1 −e)d−h + edh by operator-norm duality. Combine with
Eq. (71) and average probe ages to prove Eq. (72). The conclusive effect E+ + E−lies between zero
and identity, so its preparation/source deviations cost the same trace-distance margins, and its drift
costs Dw + Dc. The C counter proves Eq. (73).
Positivity of that rate lower bound ensures bCh + Dw −Dc > 0. Setting the right side of Eq. (72)
to zero then gives exactly Eq. (74). Its threshold can be selected from the data because the coverage
event is uniform over e. Every statement is about the nominated label marginal and holds for any
inert-reference extension of that input marginal. It is not equality of reference assemblages or of
complete quantum instruments.
For the common rate model, with mean probe age
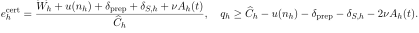
Searchable transcription
ecert
h
=
c
Wh + u(nh) + δprep + δS,h + νAh(t)
bCh
,
qh ≥bCh −u(nh) −δprep −δS,h −2νAh(t).
The absence of a subtracted confidence width in the ratio’s denominator is justified by the uniform score argument; it is not a ratio of two independent one-sided confidence intervals. The coefficients and 2
 are sharp for their respective local drift tasks: at an interior POVM change the wrong effect
 and the correct effect by
 to increase every score by
 , or decrease both effects by
 to decrease conclusive probability by 2
 . These different witnesses establish individual bounds, not simultaneous physical attainment of all statistical and drift corners.
Budget, expiry and a quantified comparison
Alternate the two templates for cycles and anchor deployment after slot
 . Their mean ages are
 + 1 and
 , hence at further age
 the worst age is
 . The common-rate numerator budget is
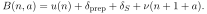
Searchable transcription
B(n, a) = u(n) + δprep + δS + ν(n + 1 + a).
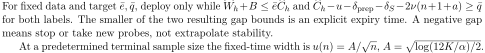
Searchable transcription
For fixed data and target  ̄e,  ̄q, deploy only while c
Wh+B ≤ ̄e bCh and bCh−u−δprep−δS −2ν(n+1+a) ≥ ̄q
for both labels. The smaller of the two resulting gap bounds is an explicit expiry time. A negative gap
means stop or take new probes, not extrapolate stability.
At a predetermined terminal sample size the fixed-time width is u(n) = A/√n, A =
p
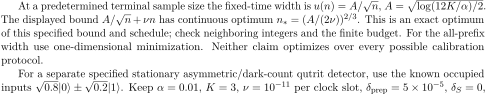
Searchable transcription
log(12K/α)/2.
The displayed bound A/√n + νn has continuous optimum n∗= (A/(2ν))2/3. This is an exact optimum
of this specified bound and schedule; check neighboring integers and the finite budget. For the all-prefix
width use one-dimensional minimization. Neither claim optimizes over every possible calibration
protocol.
For a separate specified stationary asymmetric/dark-count qutrit detector, use the known occupied
inputs
√
0.8|0⟩±
√
 . Keep
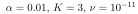 per clock slot,
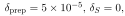 and deployment age 10
 slots. Both procedures pay actual calibration time in the same drift clock. The nine-probe example used 36 million trials and gave the arbitrary-prior certificate

 The new predetermined two-template count-table diagnostics give:
Total probe trials arbitrary-prior error bound conclusive lower bound 200,000 
 1,000,000

 2,000,000

 36,000,000


These are synthetic count tables, not experimental data or a proof of sample optimality. Their protocols have different output tasks: the nine-probe method additionally estimates a general qutrit POVM and a pointer/reference channel bound, which two templates do not identify. There is also a non-simulation sufficiency statement for this stationary benchmark law with exactly nominated calibration preparations. Write its true template means as . The same simultaneous event guarantees that the deployment gate succeeds if
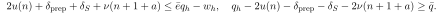
Searchable transcription
2u(n) + δprep + δS + ν(n + 1 + a) ≤ ̄eqh −wh,
qh −2u(n) −δprep −δS −2ν(n + 1 + a) ≥ ̄q.
This follows by bounding the empirical score and conclusive frequency with their opposite sides on that same absolute-confidence event. For the full-POVM arbitrary-prior targets above, per template satisfies both inequalities: one million probes suffice to guarantee deployment and the stated future conditional performance with probability at least 99 percent for this specified stationary benchmark. This is 36 times fewer trials than that nine-probe count-table demonstration, not a universal 36-fold improvement over all tomography methods or a guarantee for every drift/preparation law in the larger admitted class.
What two probes can and cannot identify
For arbitrary unknown effects, exact response on a set of target states can be determined from probe expectations if and only if the target states lie in the real linear span of the probe density matrices. Sufficiency follows by linearity. If a target lies outside that span, there is a Hermitian orthogonal to every probe and not to that target. Starting with a strictly interior POVM, perturb one effect by
 and the null effect by
 . For sufficiently small nonzero
 this remains physical, leaves every measured probe response unchanged and changes the target response. This is an exact indistinguishability counterexample, not a failed numerical search. Two distinct template density matrices are independent, so two probes are minimal for full label-response identification in this unrestricted effect model. This is not a minimum for every loose one-sided claim. Our occupied templates require only the already nominated source’s relative-mode preparations. No vacuum/occupied superposition probe is needed. Their unmeasured vacuum response remains unidentified: adding
 to a conclusive effect and subtracting it from the null is invisible to both templates. It can change another input’s response and the full qutrit measurement-channel distance. For a mixed target, an invisible traceless effect direction can likewise change a purifying reference’s conditional assemblage while preserving its label probabilities. No full-POVM or arbitrary-input diamond guarantee is claimed here. Future source deviations are charged through
 rather than assumed harmless.
Adaptive monitoring and retained records
Searchable transcription
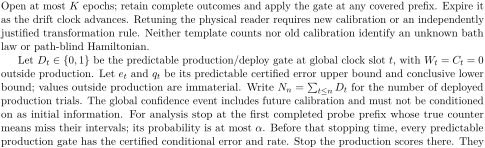
Open at most K epochs; retain complete outcomes and apply the gate at any covered prefix. Expire it
as the drift clock advances. Retuning the physical reader requires new calibration or an independently
justified transformation rule. Neither template counts nor old calibration identify an unknown bath
law or path-blind Hamiltonian.
Let Dt ∈{0, 1} be the predictable production/deploy gate at global clock slot t, with Wt = Ct = 0
outside production. Let et and qt be its predictable certified error upper bound and conclusive lower
bound; values outside production are immaterial. Write Nn = P
t≤n Dt for the number of deployed
production trials. The global confidence event includes future calibration and must not be conditioned
on as initial information. For analysis stop at the first completed probe prefix whose true counter
means miss their intervals; its probability is at most α. Before that stopping time, every predictable
production gate has the certified conditional error and rate. Stop the production scores there. They
have nonpositive conditional mean and conditional range length at most , so the exponential supermartingale with compensator
 8 gives, for any fixed
 0, a uniform record bound
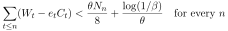
Searchable transcription
t≤n
(Wt −etCt) < θNn
8
+ log(1/β)
X
θ
for every n
with failure at most . The corresponding conclusive lower bound uses
 ; split
 if both are required. On no confidence failure the stopped and actual production records agree. Thus calibration risk is paid once across the finite budget, without conditioning on future success or inferring fresh independence. The proof filtration includes scoring truths for completed trials, while controller choices use only the permitted accessible-record subfiltration. Conditional device, source and drift promises are assumed on this augmented past, not inferred by enlarging an observed-history filtration. Known truth labels are required to score wrong outcomes in validation; an unknown production label is not made observable by this theorem. The code independently checks the continuum score identity, predictable non-iid exponential moments, the blind-direction example, exact drift coefficients and all benchmark budgets. Numerical tables corroborate the proofs and synthetic protocol; they do not certify physical drift or trusted state preparation. All source/controller, clock, null/loss, reference and correction contracts remain. No Born-selection, biological channel or consciousness mechanism is established.